证据驱动的 AI 验收系统Evidence-driven AI acceptance system· 2026
ArrivalReady
国际访客接待准备度验收系统Evidence-driven readiness assessment for international visitors
从证据采集到 AI 评估、人工复核、确定性评分和整改复测,形成一条可审计闭环。Connect evidence, AI assessment, human review, deterministic scoring, remediation, and retest in one auditable loop.
案例摘要Case summary
目标用户Audience
需要在访客到达前核对材料、发现缺口、分派整改并保留审计记录的接待团队。Hosting teams that need to check materials, find gaps, assign remediation, and retain an audit trail before a visitor arrives.
我的角色Role
负责准备度评估场景、证据与 AI 服务边界、人工复核、确定性评分、整改复测和验收标准;代码由 AI 编程工具完成。Owned the readiness scenario, the boundary between evidence and AI services, human review, deterministic scoring, remediation/retest, and acceptance criteria; code was produced with AI coding tools.
交付结果Outcome
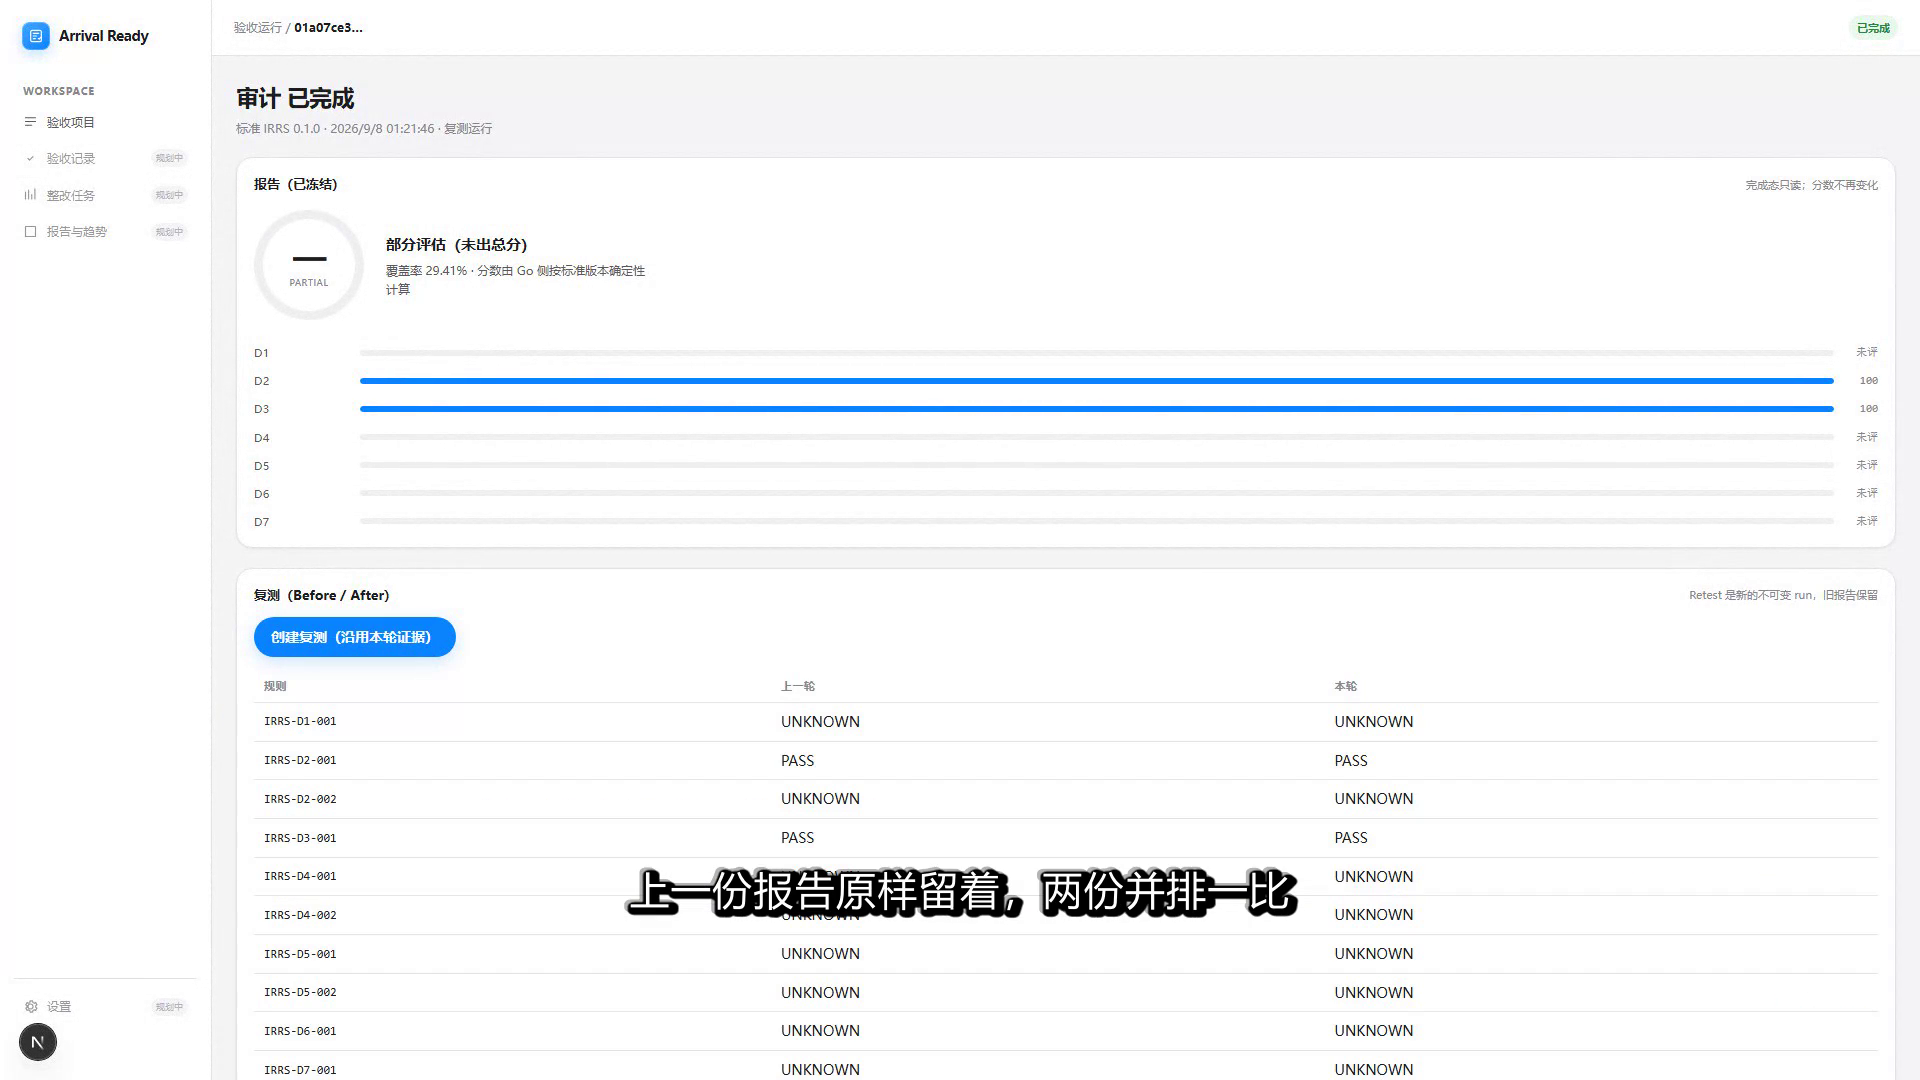
完成从证据到评估、复核、评分、整改和复测的 MVP 闭环,并保留前后差异与人工复核产物。Delivered an MVP loop from evidence to assessment, review, scoring, remediation, and retest, with before/after differences and human-review artifacts.
产品洞察Product insight
准备度评估不能只给一个模型分数。真正可交付的结果需要知道依据是什么、哪些判断由人确认、如何整改,以及复测后是否真的变好了。A readiness assessment cannot stop at a model score. A deliverable result needs its basis, human judgment, remediation path, and evidence that the retest actually improved the outcome.
项目简介Overview
ArrivalReady 面向国际访客接待准备,把分散的规则与材料转成可验证的准备度检查。系统串联 Evidence、AI assessment、human review、deterministic score、remediation 和 retest,保留前后对比与复核证据。ArrivalReady helps teams verify readiness for hosting international visitors. It connects evidence collection, AI assessment, human review, deterministic scoring, remediation, and retest while retaining before/after differences and review artifacts.
技术栈Tech stack
结果证据Evidence
仓库包含 Next.js web、Go API、FastAPI AI service、数据库迁移和测试入口,职责边界可从代码结构追溯。The repo includes a Next.js web app, Go API, FastAPI AI service, database migrations, and test entry points with traceable boundaries.
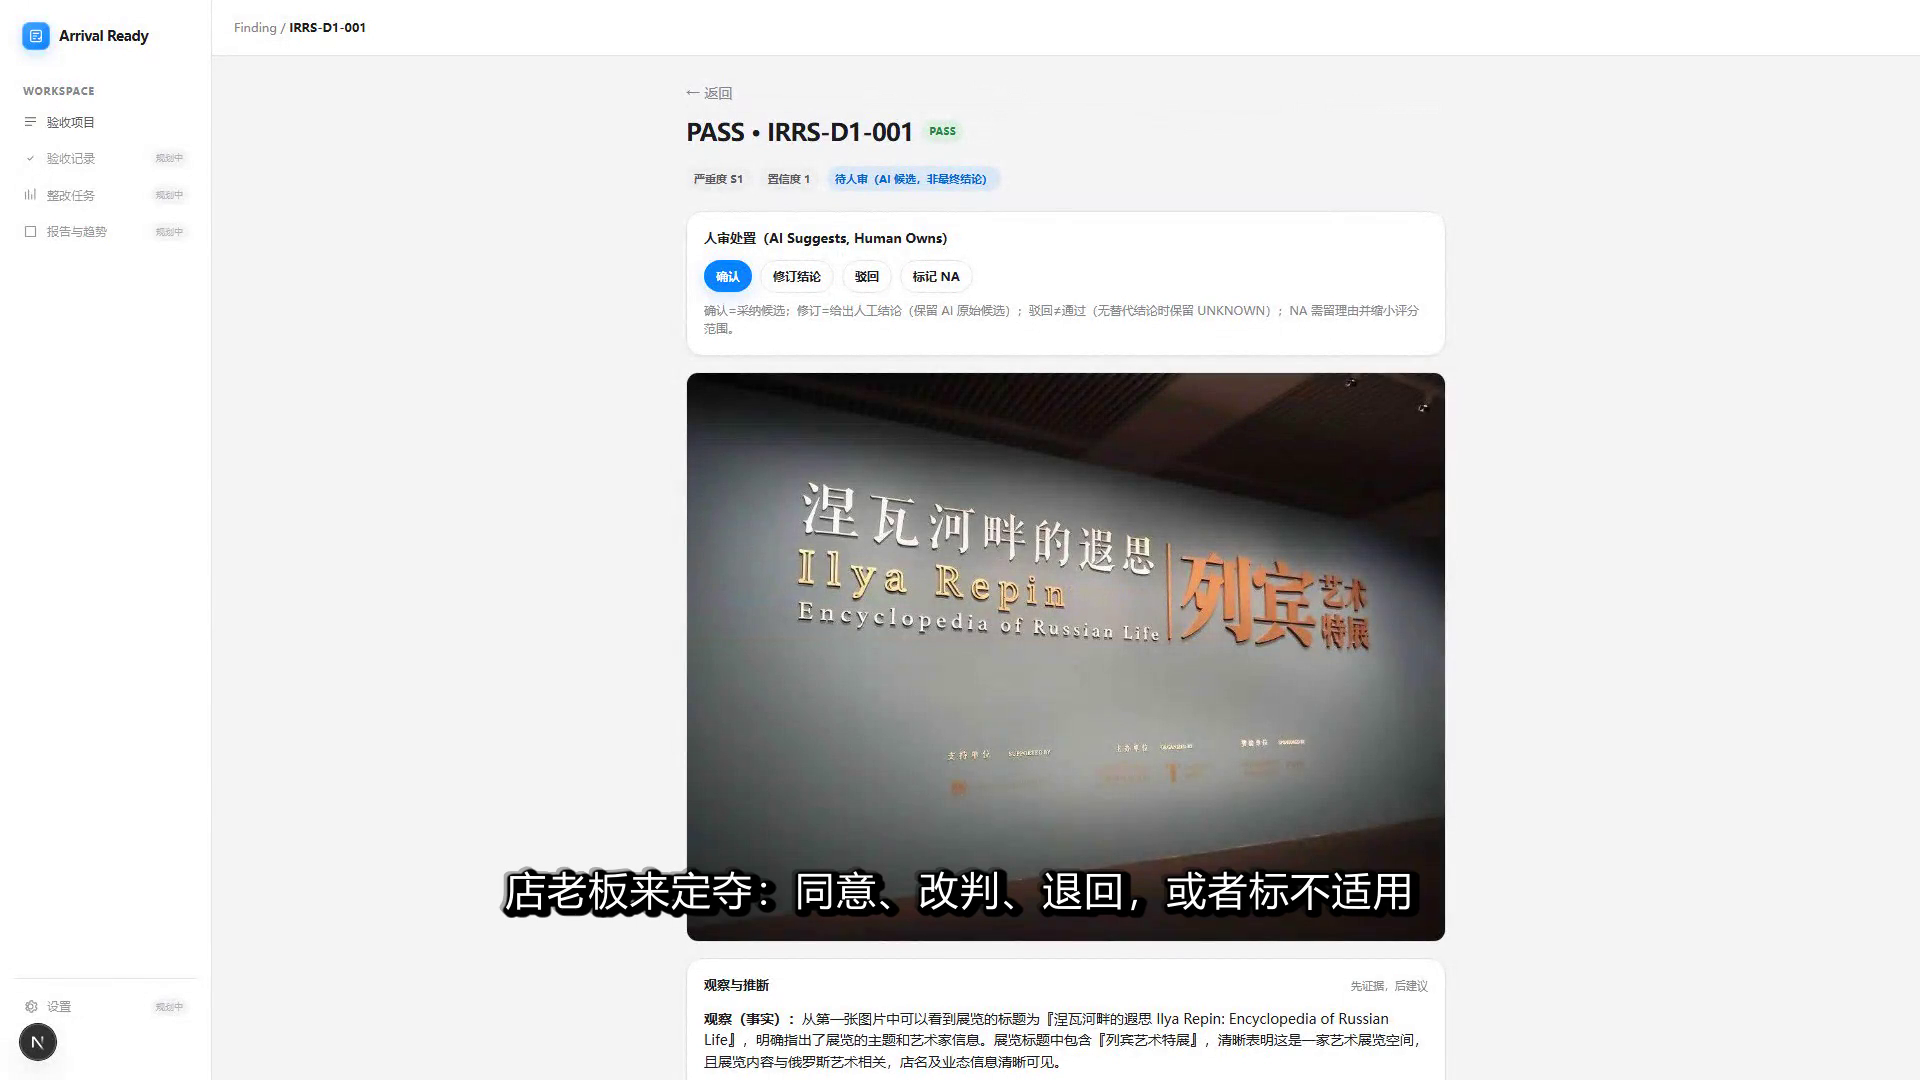
README 与产物记录 Evidence → AI assessment → human review → score → remediation → retest 的完整主流程。The README and artifacts record the Evidence → AI assessment → human review → score → remediation → retest flow.
当前仍是 MVP:URL scraping、PDF parsing 等 P0 能力未完成,也没有把固定数据与 E0–E1 阶段证据表述为真实用户验证。This remains an MVP: URL scraping and PDF parsing are unfinished P0 work, and fixed data or E0–E1 artifacts are not presented as real-user validation.
项目截图Screenshots
关键决策Key decisions
模型判断具有概率性,直接让模型写入业务结果会让评分、整改和复测失去可复核性。Model judgments are probabilistic; letting a model write business outcomes directly would make scoring and retest hard to review.
AI 只负责抽取与评估,最终 Gate 和分数由确定性规则与人工复核共同决定。Keep AI responsible for extraction and assessment while deterministic rules and human review decide the final Gate and score.
整改完成不代表准备度真的提升,单次评估无法形成闭环。Completing remediation does not prove readiness improved; a single assessment cannot close the loop.
把 remediation 与 retest 作为一等流程,并保留 before/after 差异用于复盘。Make remediation and retest first-class flows and retain before/after differences for review.
想看完整的代码和实现细节?Want the full code and implementation details?
在 GitHub 上查看View on GitHub